AI evaluation
Model comparisons, answer-quality tests and error analysis. The outcome: a clear view of what a system can and cannot do.
↗
Mateusz WiecekAI · Lifestyle
AI evaluation · Machine learning · RAG
I build and test AI systems, from document retrieval to image recognition. I show what works, where a system fails and what to improve, bringing experience from sport and leading teams to the way I work.
Strathclyde, physical education and Smile Camp. Technical precision meets the energy of sport and experience working with people.
About
I have completed the requirements for the MSc Artificial Intelligence and Applications at the University of Strathclyde. The formal award is pending. My route runs from physical education, football and group leadership to building AI systems. Curiosity, patience and responsibility for the outcome connect those worlds.
How I can help
Looking for help with an AI project or someone to join your team? These are the problems I work on.
Model comparisons, answer-quality tests and error analysis. The outcome: a clear view of what a system can and cannot do.
↗Prototypes for document retrieval, classification and prediction. The outcome: a reproducible experiment with code and metrics.
↗I combine technical work with experience leading sports groups. I explain complex ideas clearly and turn them into practical next steps.
↗Evidence over promises
Selected metrics from academic projects. Every number has a defined dataset, evaluation method and limitations.
How I work
I do not treat a model score as decoration. First I define what we are really measuring, then I build a repeatable experiment and present the result together with its limitations.
retrieval over a synthetic EHR dataset
Method and limitation +How it was tested: Qrels and explicit P@3, R@3 and MRR for patient-specific retrieval.
Limit: This is not 100% answer quality or clinical effectiveness. The data is synthetic.
Project source ↗primary result on original test labels
Method and limitation +How it was tested: A feed-forward network built in NumPy, with regularisation, early stopping and error analysis.
Limit: Label alignment gives a diagnostic 88.62%; it does not replace the primary 45.84% result. This is an image benchmark, not camera-based gesture recognition.
Project source ↗reported regression-model error
Method and limitation +How it was tested: CatBoost, baselines, feature engineering, validation, diagnostic figures and tests.
Limit: The result depends on the dataset and target scale; it is not a recommender-system score.
Project source ↗with 9.99% maximum drawdown
Method and limitation +How it was tested: Chronological train/test evaluation, transaction costs and several comparison baselines.
Limit: A historical experiment, not a forecast of future returns or investment advice.
Project source ↗Experience
From people and communication, through demanding operations, to reproducible AI systems — each experience reinforces responsibility for the outcome.
2012—present · seasonal
Since 2012, I have contributed seasonally to the Smile Camp experience, combining camp and sports leadership with web content and digital communication support.
Meet the team↗2025–2026 · formal award pending
Artificial Intelligence and Applications. From neural-network experiments to a dissertation on evidence retrieval in clinical records.
Explore my story and research↗2019—present
High-tempo operational work requiring routing accuracy, procedural compliance, independent judgement and effective exception handling.
More than a calling card
Four paths lead from a concise introduction to inspectable projects, current focus and publication-ready material.
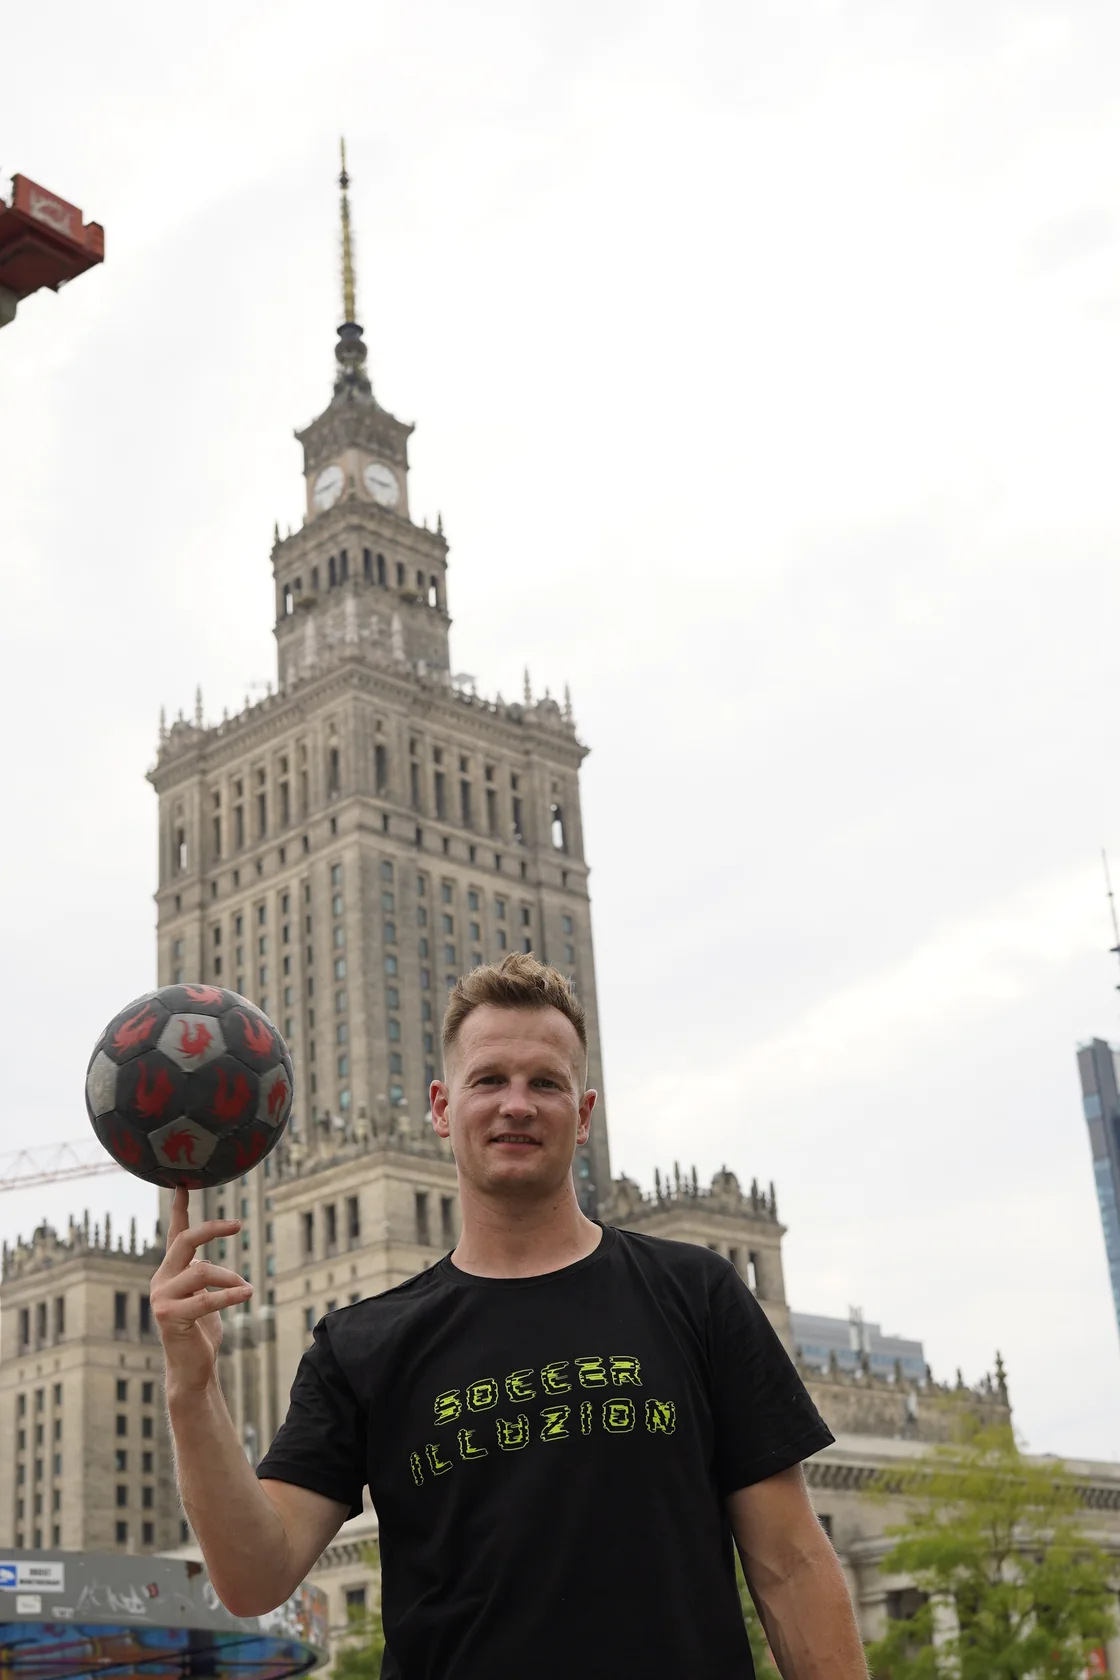
Beyond the screen
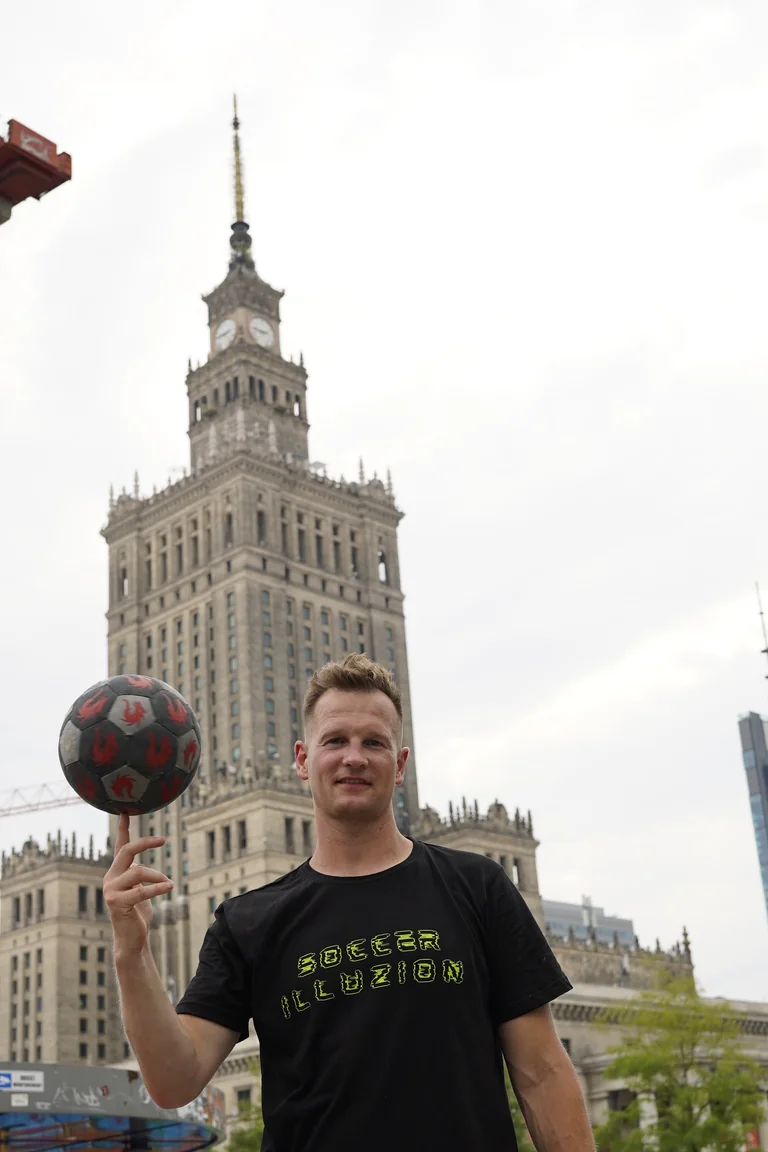
Sport is not an accessory to my work. Physical-education training, football, freestyle football and leading groups of young people have taught me focus, calm and responsibility for others — the same qualities I bring to technology.
Movement, focus and consistency.
Leading groups and creating a positive atmosphere.
Connecting distant fields into new ideas.
Latest thinking
Sport, three Strathclyde projects and a small pose-estimation experiment. Why a good result needs an honest context.
Read→How a cryptographic enclave can test a closed model independently without exposing either its weights or the questions.
Read→What Anthropic’s disclosure teaches us about isolation, permissions and monitoring for long-running AI agents.
Read→Start a conversation
An AI project, a role, education or sport? Tell me what you are working on, your goal and the support you need. We can talk in English or Polish.
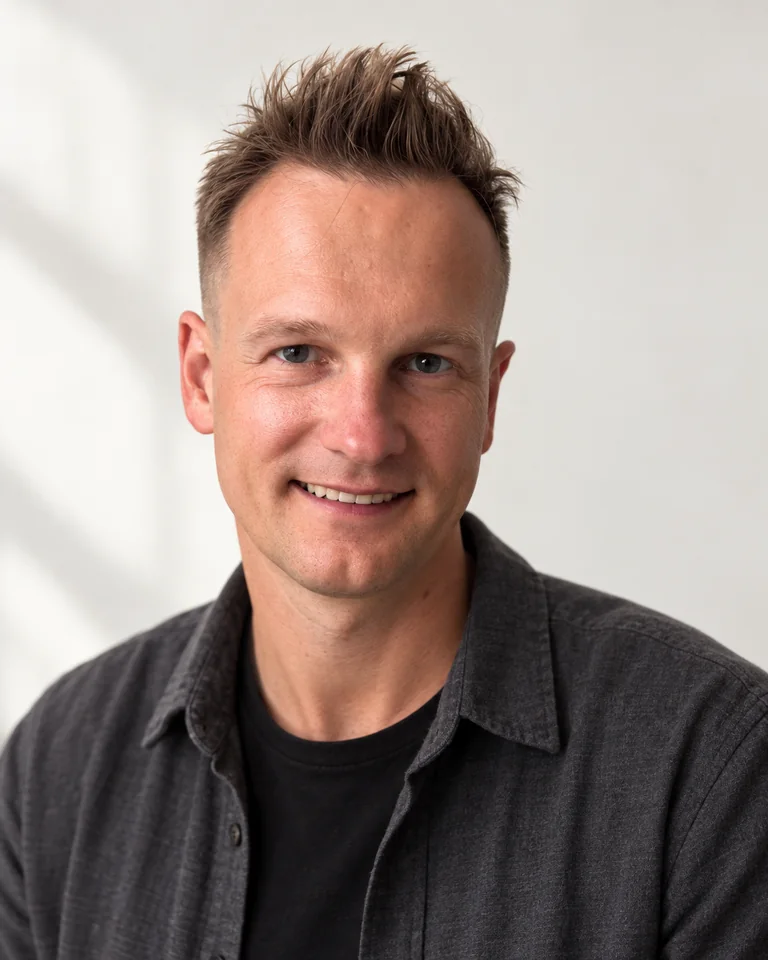
Send me a message or a connection request with a little context. You can explore the projects and code before we talk.
Open LinkedIn↗Explore projects and results→